The People's Choice of Top LLM Evaluation Tools in 2025
A hand-picked, carefully curated list of the best LLM evaluation tools in 2025, compared on metrics, features, and pricing to help you choose the right one.
What is LLM Observability? - The Ultimate LLM Observability Guide
LLM observability is the practice of tracing, monitoring, and evaluating LLM apps in production. Learn what it covers and what to look for when choosing a tool.
Top LLM Chatbot Evaluation Metrics: Conversation Testing Techniques
Evaluate LLM chatbots with metrics for relevancy, coherence, and safety, plus multi-turn conversation testing that measures quality across a full dialogue, not one reply.
LLM-as-a-Judge Simply Explained: The Complete Guide to Run LLM Evals at Scale
Complete guide to LLM-as-a-Judge: how it works, single-output vs pairwise scoring, G-Eval, DAG, prompting techniques, and how to use LLM judges for scalable LLM evaluation.
Evaluating LLM Systems: Essential Metrics, Benchmarks, and Best Practices
Learn how to evaluate LLM systems using LLM evaluation metrics, benchmark datasets, and best practices — with practical DeepEval code examples to get started.
Using LLMs for Synthetic Data Generation: The Definitive Guide
Everything you need to generate realistic synthetic datasets with LLMs: data evolution techniques, quality filtering, and code to build datasets from scratch.
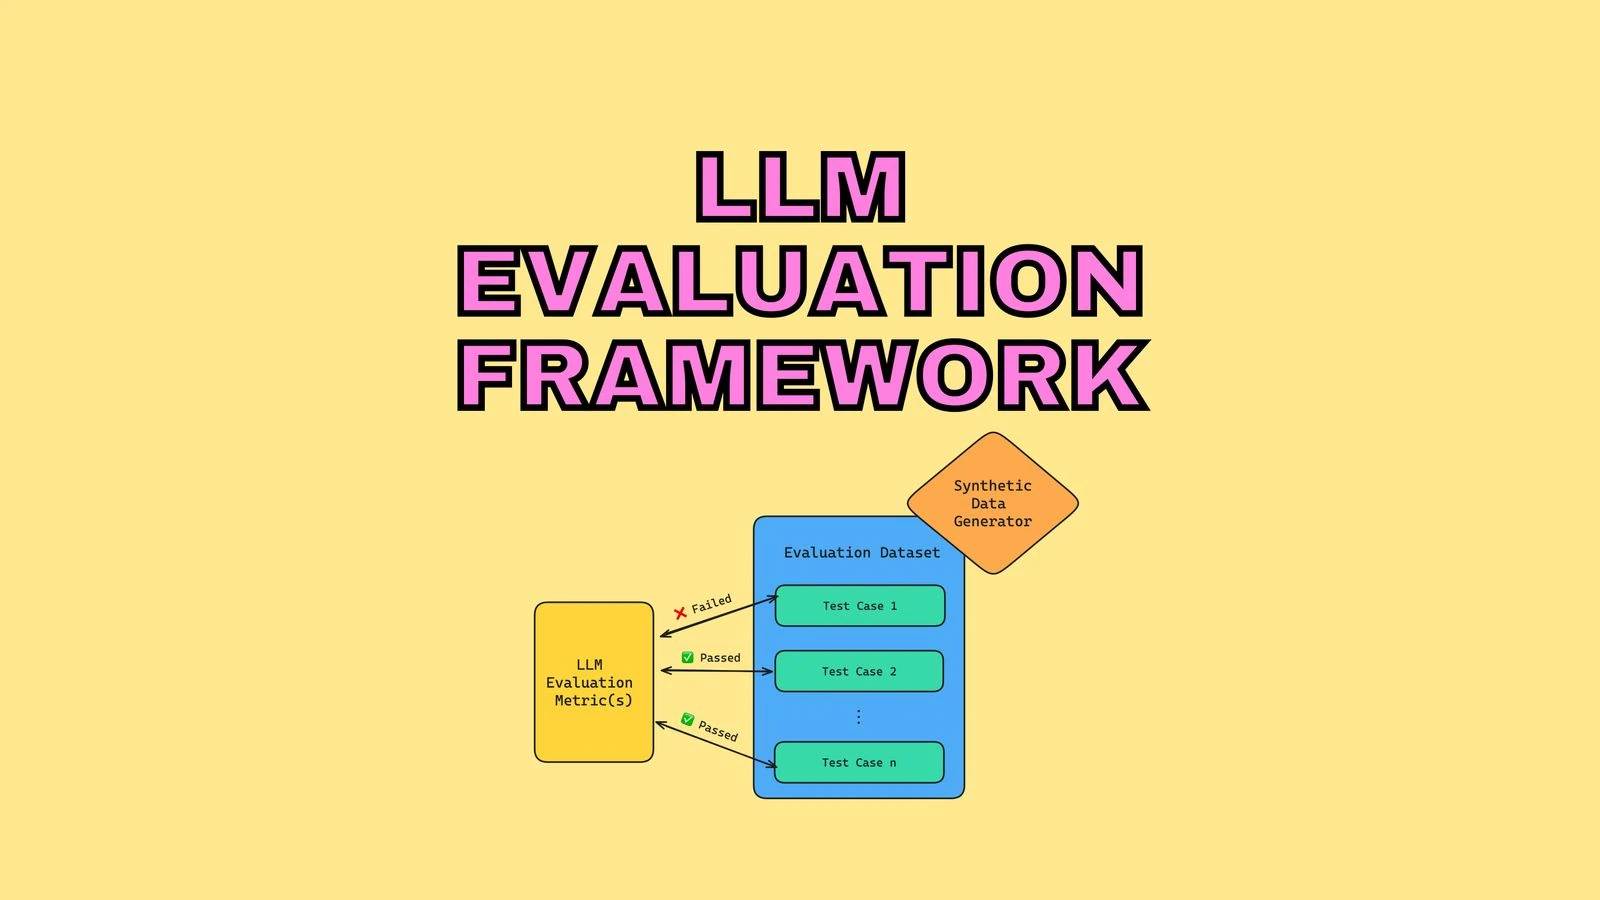
How to Build an LLM Evaluation Framework, from Scratch
A step-by-step guide to building a robust, scalable LLM evaluation framework from scratch — metrics, test cases, and architecture, with DeepEval code examples.
Top LLM Benchmarks Explained: MMLU, HellaSwag, BBH, and Beyond
MMLU, HellaSwag, BBH, and beyond: what each top LLM benchmark measures, its limitations, and why these scores matter when choosing a model to build on.
LLM Testing in 2026: Top Methods and Strategies
LLM testing in 2026 spans unit-testing prompts, end-to-end evals, and regression tests. Learn the top methods, strategies, and best practices for testing LLMs at scale.
The Ultimate Guide to Fine-Tune LLaMA 3, With LLM Evaluations
Fine-tune LLaMA with Hugging Face, then use DeepEval and LLM evaluation metrics to measure whether the fine-tuned model actually improved over the base model.