Voice AI teams have been forced to choose between tools that understand audio and tools that understand AI systems. The result is usually a fragmented stack: one product for voice-specific testing, another for general AI evaluation, and another for production observability. Today, we're launching Voice AI Evals on Confident AI so the full quality workflow can live in one place — for the engineers building the system and the product managers, QA teams, and domain experts responsible for how it performs.
This unlocks a new class of testing on Confident AI. You can now evaluate not only what a voice agent says, but how the entire conversation sounds and behaves.
A voice agent is more than its transcript
A transcript can tell you whether an agent gave the right answer. It cannot tell you whether the caller could understand it, whether the voice changed halfway through a sentence, or whether the agent talked over someone trying to interrupt.
That distinction matters because users experience a voice agent as a conversation, not a sequence of text outputs. An agent can be factually correct and still feel broken because it responds too slowly, misses a turn, struggles with background noise, or sounds unnatural.
Voice AI Evals let you test that complete experience. Run persona-based simulations to see how the agent handles different callers and scenarios, then introduce the conditions that make real conversations difficult: interruptions, background noise, changing turn patterns, and more.
Instead of testing the ideal call, you can test the calls your agent will actually receive.
Seven metrics for the voice experience
Confident AI now includes seven voice-specific metrics:
- Voice Naturalness
- Speech Intelligibility
- Voice Consistency
- Turn-Taking Naturalness
- Agent Responsiveness
- Audio Integrity
- Voice Reliability
These metrics evaluate the audio files themselves and are fully deterministic, giving teams repeatable signals for the parts of a conversation that a transcript cannot capture. They sit alongside Confident AI's existing LLM-as-a-judge multi-turn metrics, so you can evaluate conversation quality, task performance, and the voice experience in the same test run.
That means one evaluation can answer both sides of the problem: Did the agent handle the conversation correctly? and Was the conversation actually usable?
Connect to the voice stack you already use
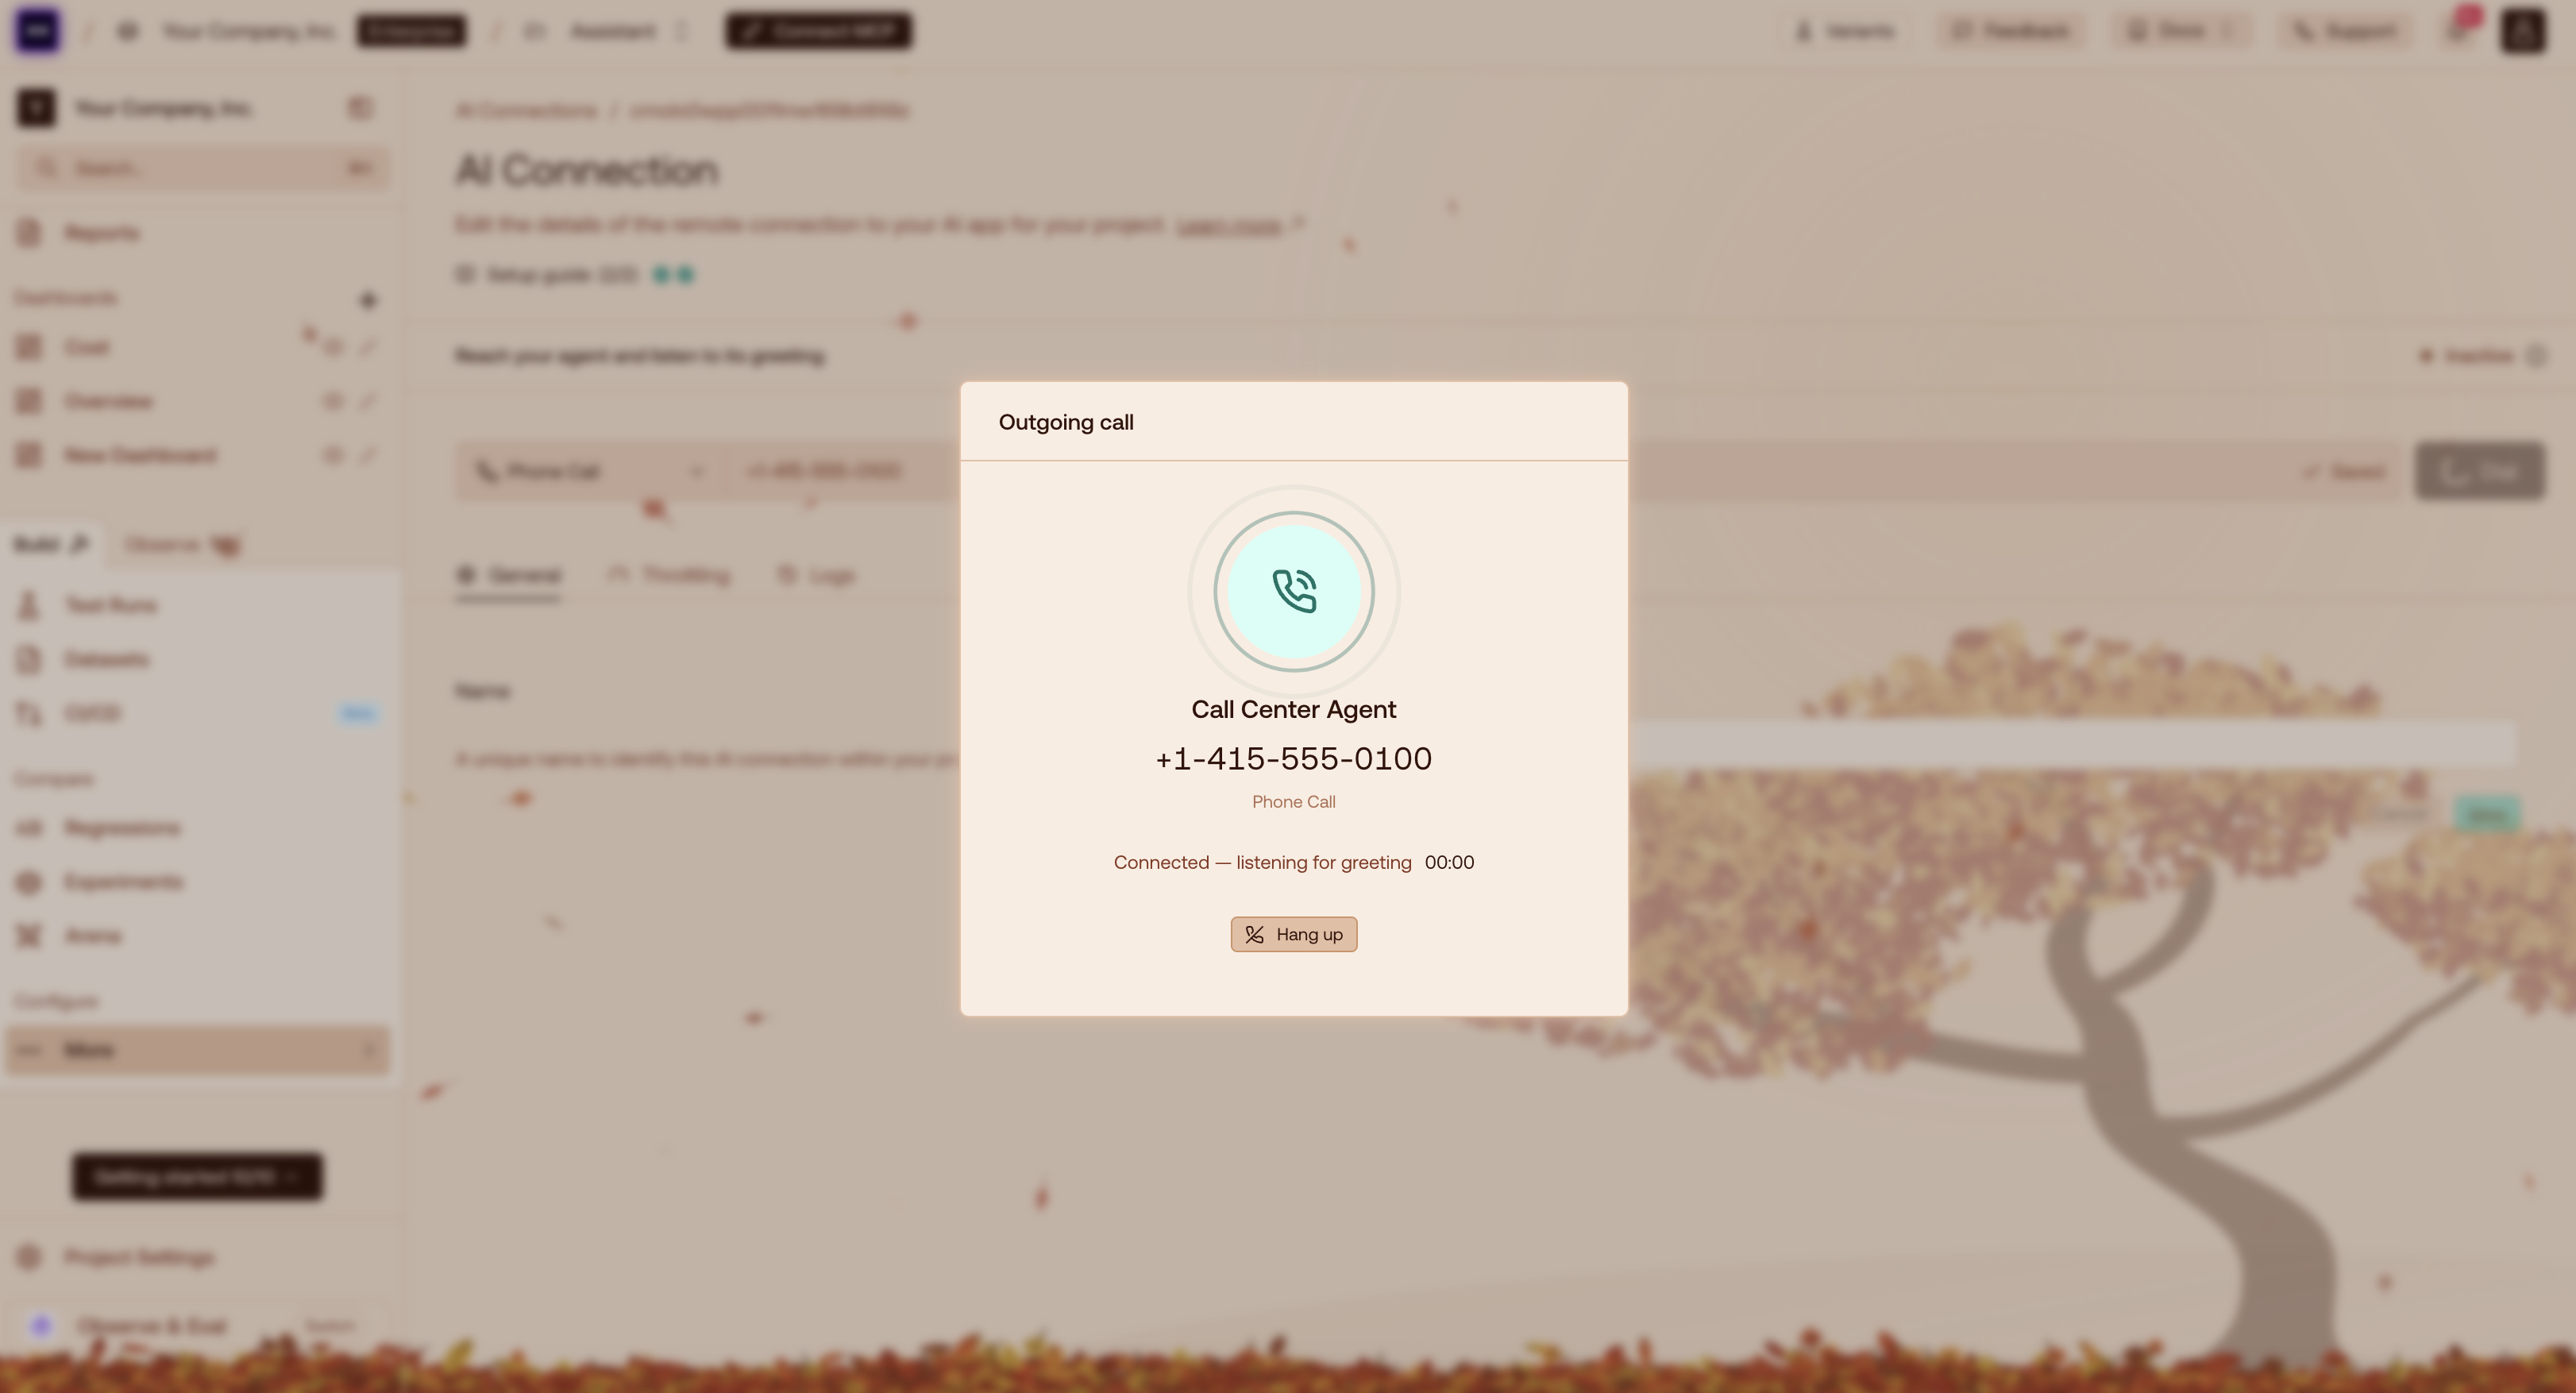
You should not have to rebuild your voice infrastructure to evaluate it. Confident AI supports SIP, phone calls, WebRTC, and WebSockets, with LiveKit integrations that let you dial into agents built with platforms such as Vapi and ElevenLabs and test pipelines using OpenAI speech-to-text and text-to-speech models.
Connect the agent, define the personas and scenarios you care about, and run the same evaluation workflow across the rest of your AI stack.
One quality workflow for the whole team
The larger shift is consolidation.
Voice quality should not live in a specialist tool that only one team can use while transcripts, traces, datasets, annotations, and production metrics live somewhere else. Every handoff between those systems creates another export, another dashboard, and another version of what "good" means.
With Voice AI Evals on Confident AI, technical and non-technical teams work from the same evidence. Engineers can diagnose the call and trace behind a failure. QA teams and domain experts can review conversations and annotate what happened. Product teams can compare performance across personas and scenarios without maintaining a separate evaluation stack.
Voice is now a first-class part of the same evaluation and observability workflow you already use for the rest of your AI system.
Get started
Voice AI Evals are live on Confident AI now.
Connect your voice agent, create a persona-based test, and start evaluating the conversation your users actually experience. Book a demo with the Confident AI team to see it in action.
Do you want to brainstorm how to evaluate your LLM (application)? Ask us anything in our discord. I might give you an "aha!" moment, who knows?
Standardize AI Quality for the entire org, not just individual teams
Give all AI use cases the same quality bar with all-in-one evals, observability, and red teaming, and enforce them at scale.