Most teams evaluate a tiny fraction of their production traffic.
Not because they want to. Every online eval on a trace and every sentiment label on a conversation is a judge call, and judge calls cost money. So sample rates get set to 1%, and the other 99% of production goes unscored and unclassified.
That creates a ceiling on everything built on top. A regression that affects one segment of traffic may never show up in a 1% sample. A correlation between an issue and negative sentiment needs enough labeled traces to be visible. A customer with a bad week may have only a handful of classified conversations.
So today, for Day 5 of Launch Week 03, we're launching Jev-as-a-Judge on Confident AI. It makes judge decisions fast and cheap enough that you can stop rationing them.
Stop sampling evals on 1% of live traffic
With Jev-as-a-Judge, the workflows you already run on Confident AI can cover far more of your live traffic:
- More online evals on traces: score 20%, 50%, or more of production instead of a thin slice
- More sentiment analysis on traces and threads: classify most conversations, not a handful
- More classification across every dimension: issues, use cases, and safety labels on the traffic that matters
Same evaluation rules, same classifiers, same workflows. You just turn the sample rate up.
More coverage, more insights
Every insight on Confident AI is limited by how much of your traffic has been scored and labeled. Raise the coverage and every downstream workflow gets sharper:
- Drift has more evaluated traces per agent configuration, so regressions reach significance sooner and smaller segments of live traffic become visible
- Category Correlation has more labeled traces and threads, so relationships between issues, sentiment, and use cases stand out from the noise
- Customer Monitoring has a complete picture of each account's sentiment and issues, not a sample of it
- Signals catches spikes in classifier labels earlier, because more of the traffic behind them is classified
The insights no longer depend on whether the right trace happened to land in the sample.
What is Jev?
Jev is TypeSafe AI's System One model. It is not a language model. You give it some state and a bounded question, such as whether a response is supported or which label fits, and it returns a decision with a probability.
Most of an eval is a decision like that, not a writing task. Jev takes over those decisions while the LLM keeps the language work, which makes each judgment:
- Cheap: $0.042 per million input tokens, with no charge for output tokens
- Fast: most decisions complete in roughly 100 ms
- Consistent: the same trace gets the same verdict, so trends reflect your agent, not judge noise
The tradeoff: because Jev is not a chat model, it does not write out its reasoning. You get the verdict and its probability, not an explanation.
Get started
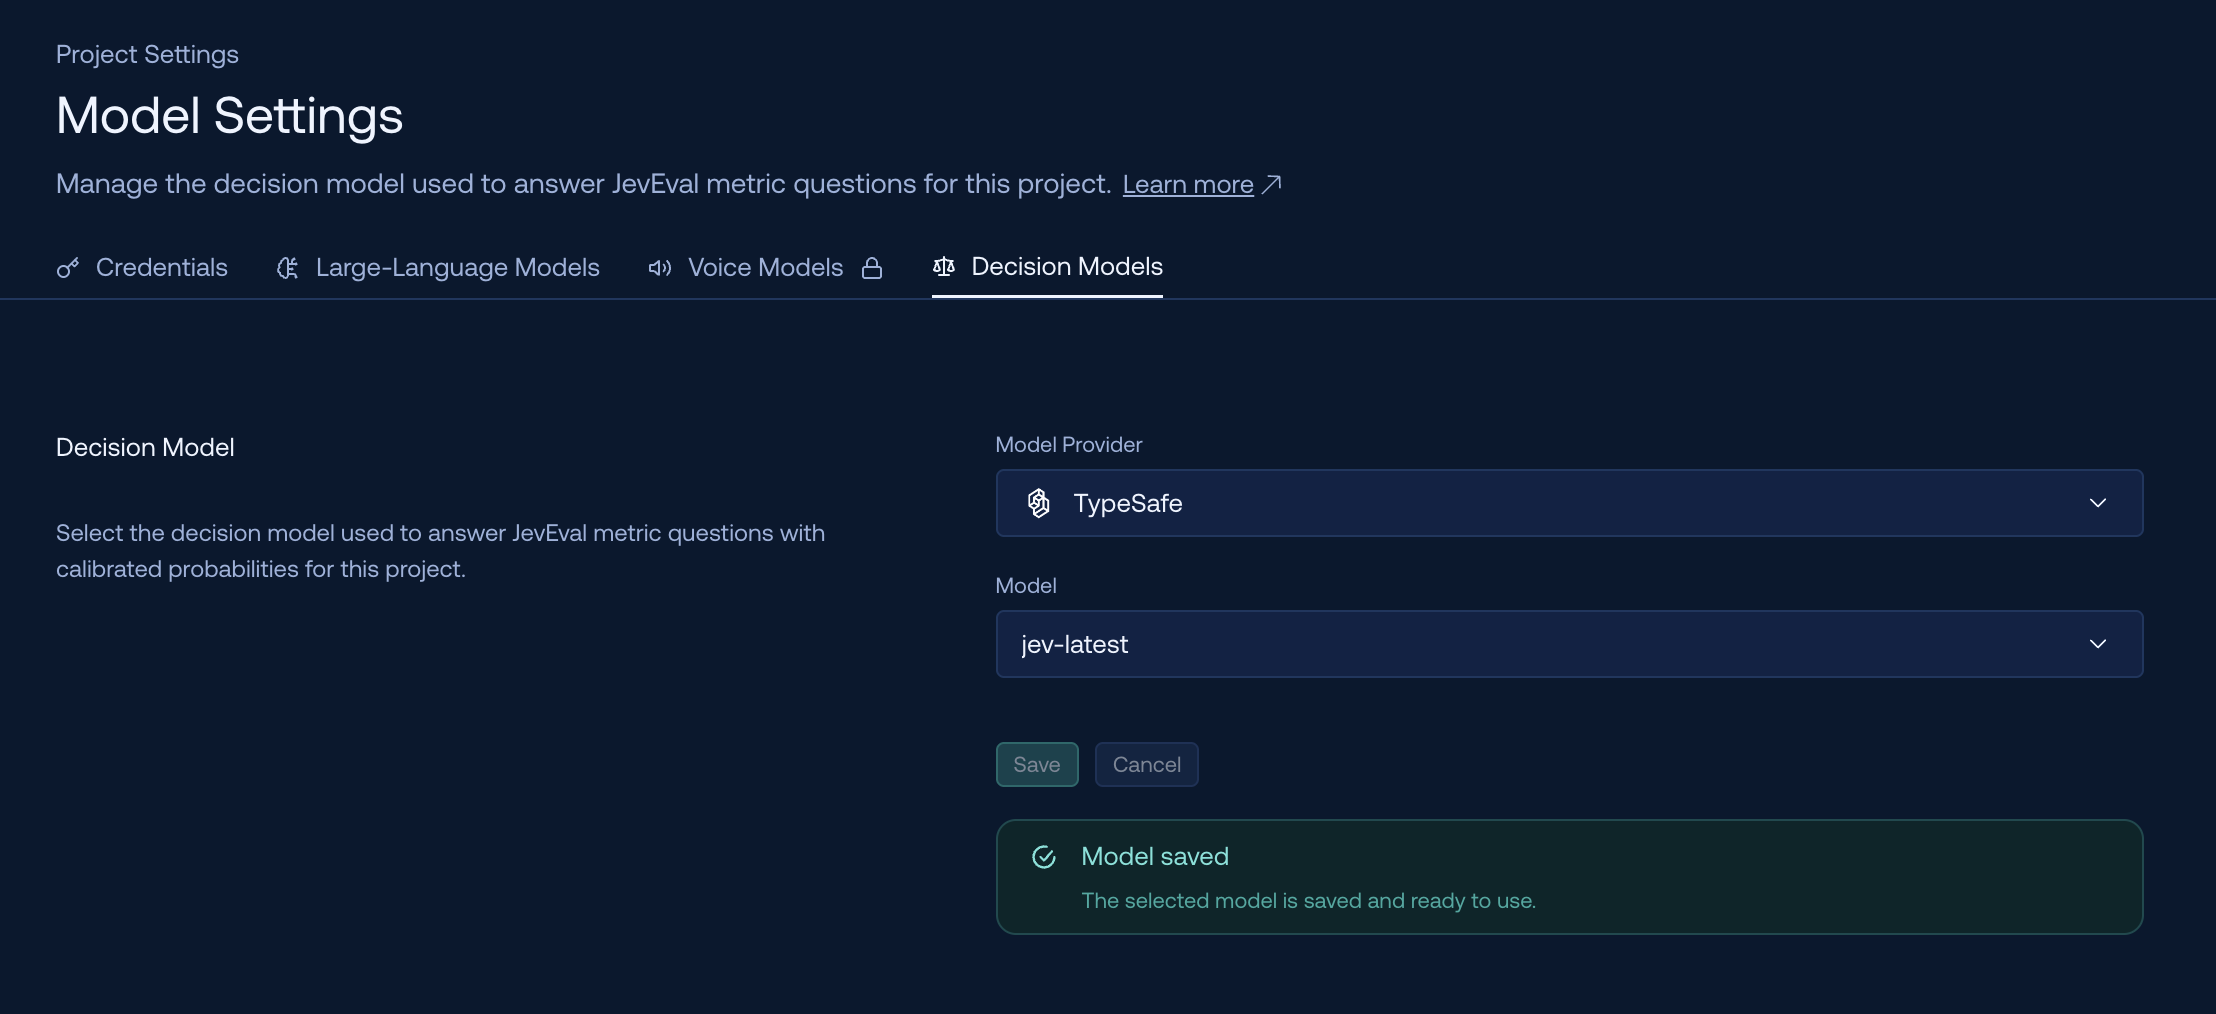
Jev-as-a-Judge is live on Confident AI now. Open Project Settings → Model Settings → Decision Models, select TypeSafe as the provider and jev-latest as the model, then raise the sample rates you have been keeping low.
Jev is also available in DeepEval, our open-source evaluation framework. For the technical walkthrough, read Introducing Jev in DeepEval.
Book a demo with the Confident AI team to see Jev-as-a-Judge in action.
Do you want to brainstorm how to evaluate your LLM (application)? Ask us anything in our discord. I might give you an "aha!" moment, who knows?
Standardize AI Quality for the entire org, not just individual teams
Give all AI use cases the same quality bar with all-in-one evals, observability, and red teaming, and enforce them at scale.