Stay Confident.
The latest developments, best practices and deep dives on AI evals.
A step-by-step guide to MCP evaluation: how to test MCP-based LLM apps and agents, measure tool use and task completion, and catch failures with DeepEval.
A practical guide to evaluating AI agents with LLM metrics and tracing—plus when human review matters, how it calibrates judges, and workflows that combine CI, sampling, and production signals.
Everything you need to run LLM Arena-as-a-judge: a comparison-based, pairwise approach to regression testing LLMs, with DeepEval code to set it up.
RAG evaluation metrics — answer relevancy, faithfulness, and contextual relevancy — measure retrieval and generation quality, with working DeepEval code examples.
Most LLM evals fail because their metrics don't predict ROI. This playbook shows how to build outcome-based evals that correlate with real business KPIs and user value.
The definitive guide to G-Eval: how this LLM-as-a-judge metric works, chain-of-thought scoring, and how to evaluate LLM apps on custom criteria with DeepEval.
A rundown of the top LLM evaluators for testing at scale in 2025, from G-Eval and other LLM-as-a-judge metrics to the tooling that runs them in production.
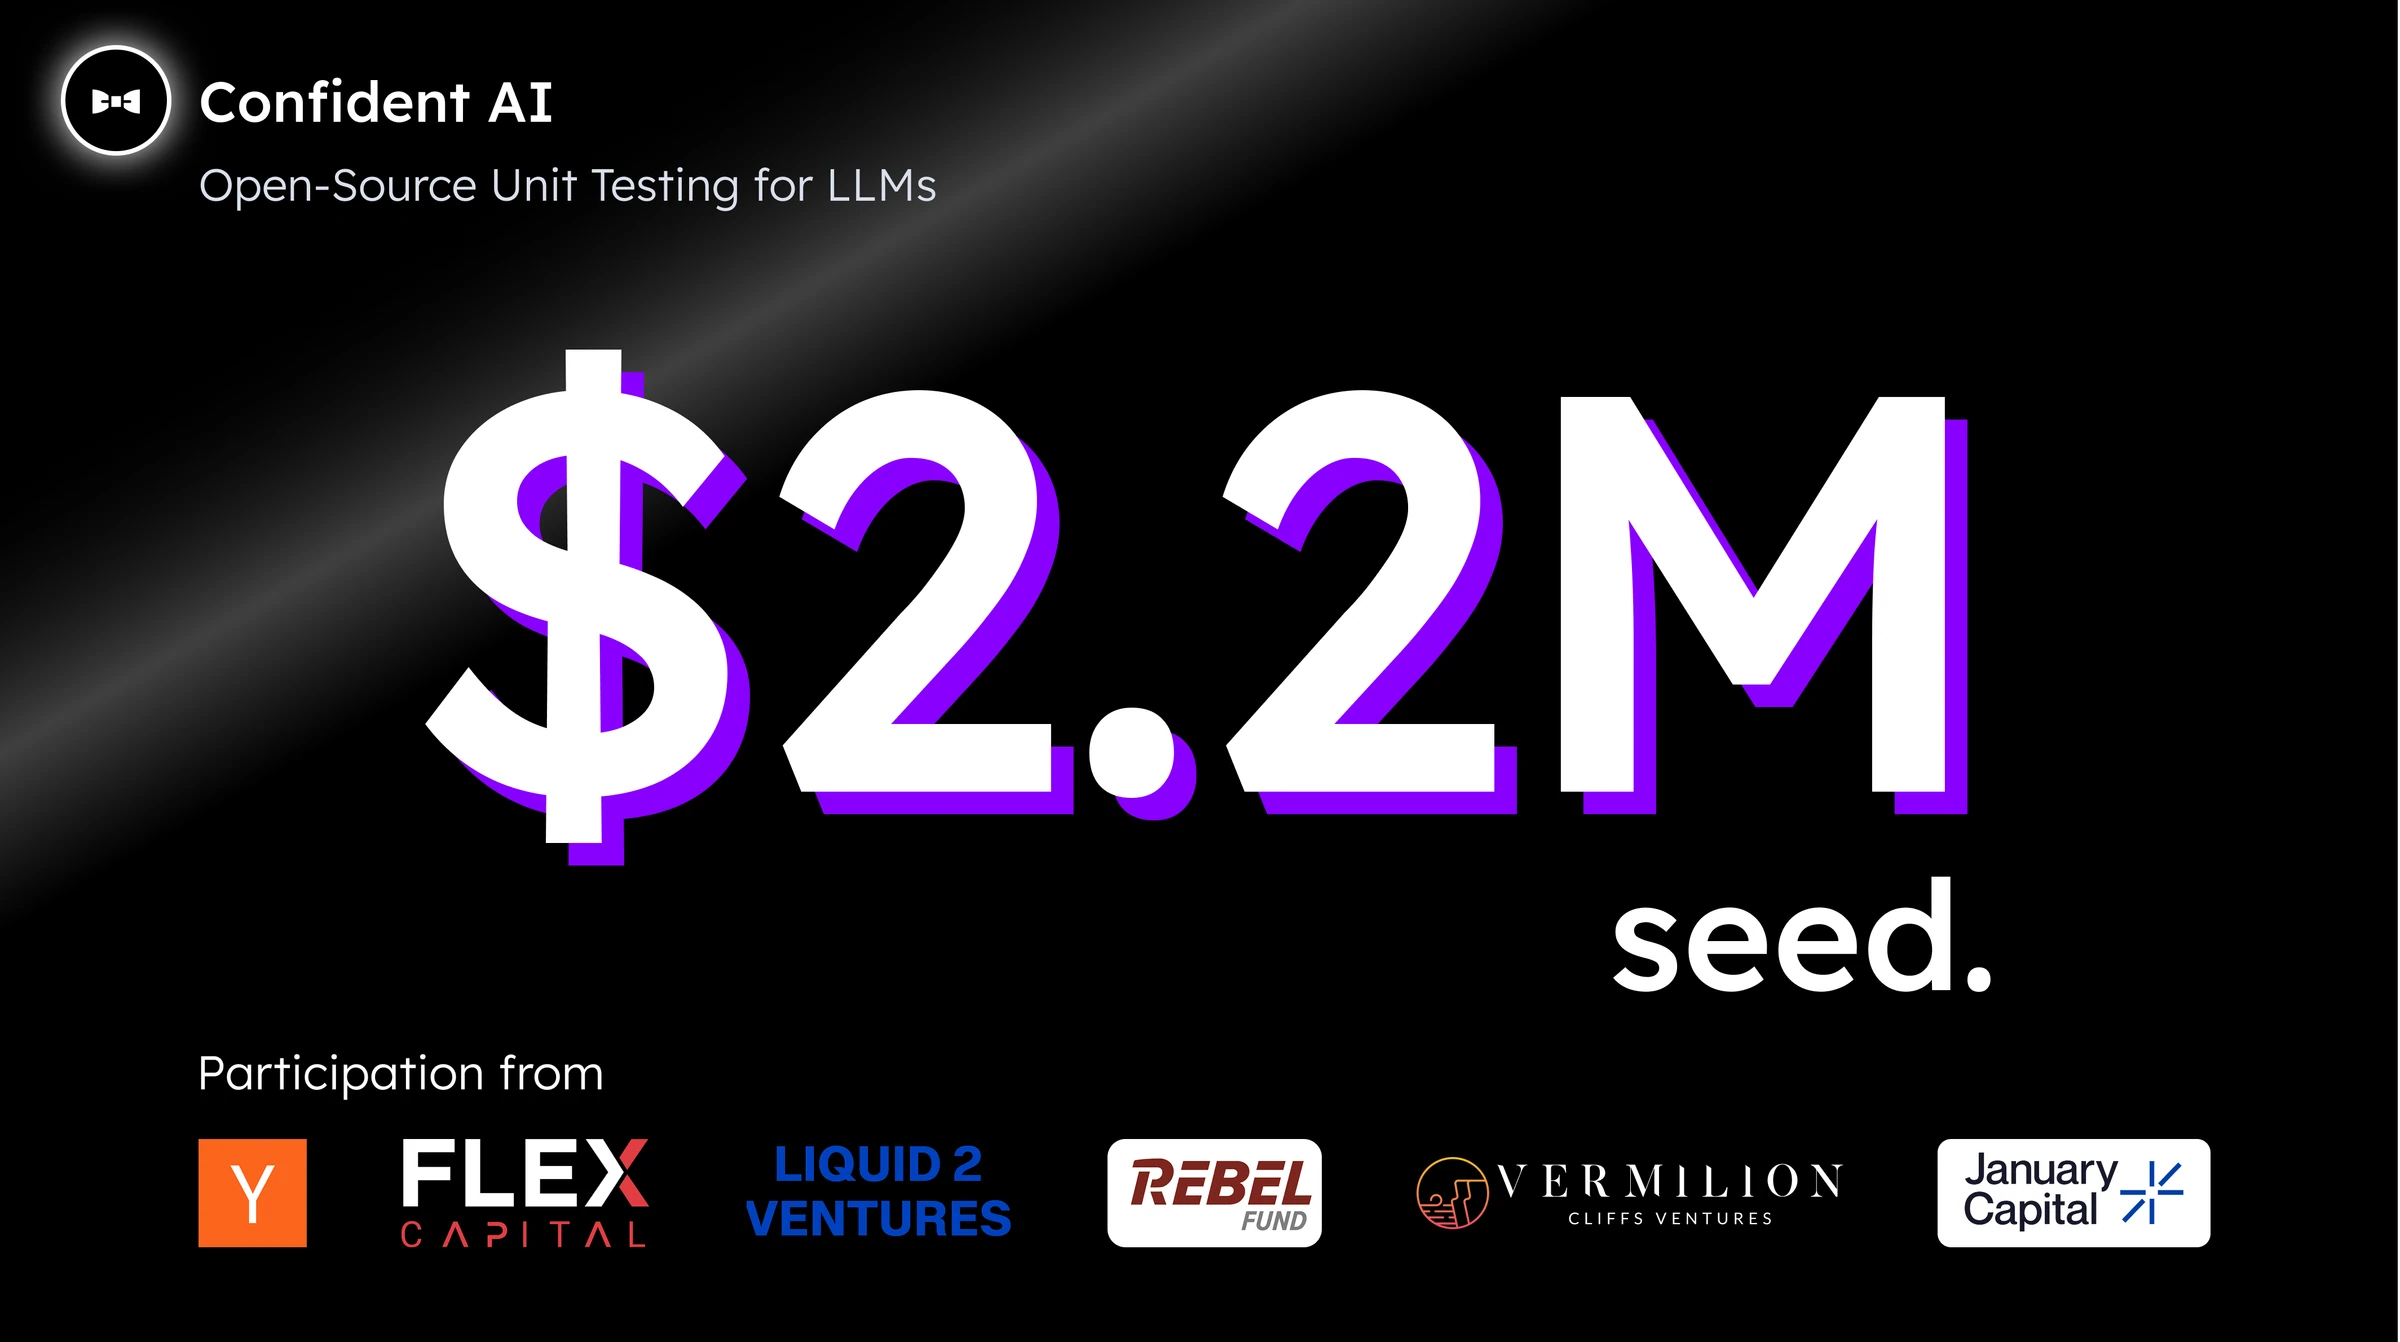
Confident AI raised an oversubscribed $2.2M seed round in 5 days. Here's the fundraising strategy, the investor conversations, and the hard lessons from the raise.
DeepEval's DAG metrics make LLM-as-a-judge scoring deterministic by running outputs through a decision tree. Here's how I built these reliable, explainable metrics.
Learn how to evaluate LLM agents end-to-end with tool calling, task completion, reasoning, trace-based evals, human review, and DeepEval code examples.