



November 6, 2026
- Observability
- Evals
- Integrations
- Security
- Red Teaming
Can You Hear Me Now?
TGIF! Thank god it's features, here's what we shipped this week:
Your voice agents just got a lot easier to listen to. ElevenLabs is now a first-class integration, and every voice simulation now leaves a full trace behind, so you can follow a simulated call from the first "hello" to the last span. Voice connections can carry your own metadata into every call, LiveKit simulations pick up agent state events, and every call log now tells you how the call ended. Audio from LLM spans plays right inside the messages view. Read it, hear it, trace it. Your agent has a lot to say, and now you won't miss a word.
Added
- ElevenLabs Integration - Connect your ElevenLabs agents to Confident AI and test, trace, and evaluate them alongside the rest of your voice stack. We turned it up to eleven.
- Traceable Voice Simulations - Every voice simulation now produces a trace, so you can inspect each turn, span, and tool call behind a simulated conversation. No call goes untraced.
- Metadata in Voice Connections - Send your own metadata with every call: dispatch metadata for LiveKit, the request body for Pipecat, and more. Every call now comes with context clues.
- Agent State Events in the LiveKit Simulator - The LiveKit voice connection simulator now accepts agent state events, so simulations know when your agent is listening, thinking, or speaking. Finally, a read on your agent's state of mind.
- End Reasons in Voice Connection Logs - Voice connection logs now record why each call ended. Every story deserves a proper ending.
- Online Evals Wait for Late-Arriving Spans - Online evals now wait for traces that are still arriving before scoring them, so late OpenTelemetry spans make it into the eval. Better late than never, and now never scored too early.
- Separate Thread & Trace Idle Time for Online Evals - Idle time for online evals is now split into thread idle time and trace idle time, so you can tune each one on its own. Time well split.
- Journey Discovery from Annotation Queues - Discover journeys straight from your annotation queues, turning your reviewers' notes into paths through your product. Every annotation is a stop on the map.
- Hardcoded User Messages in Journey States - Journey states can now include a hardcoded user message, so you control exactly what the user says at that step. Some lines are better scripted.
- Filter Goldens During an Evaluation - Pick which goldens to run when you kick off an evaluation. All that glitters, now filtered.
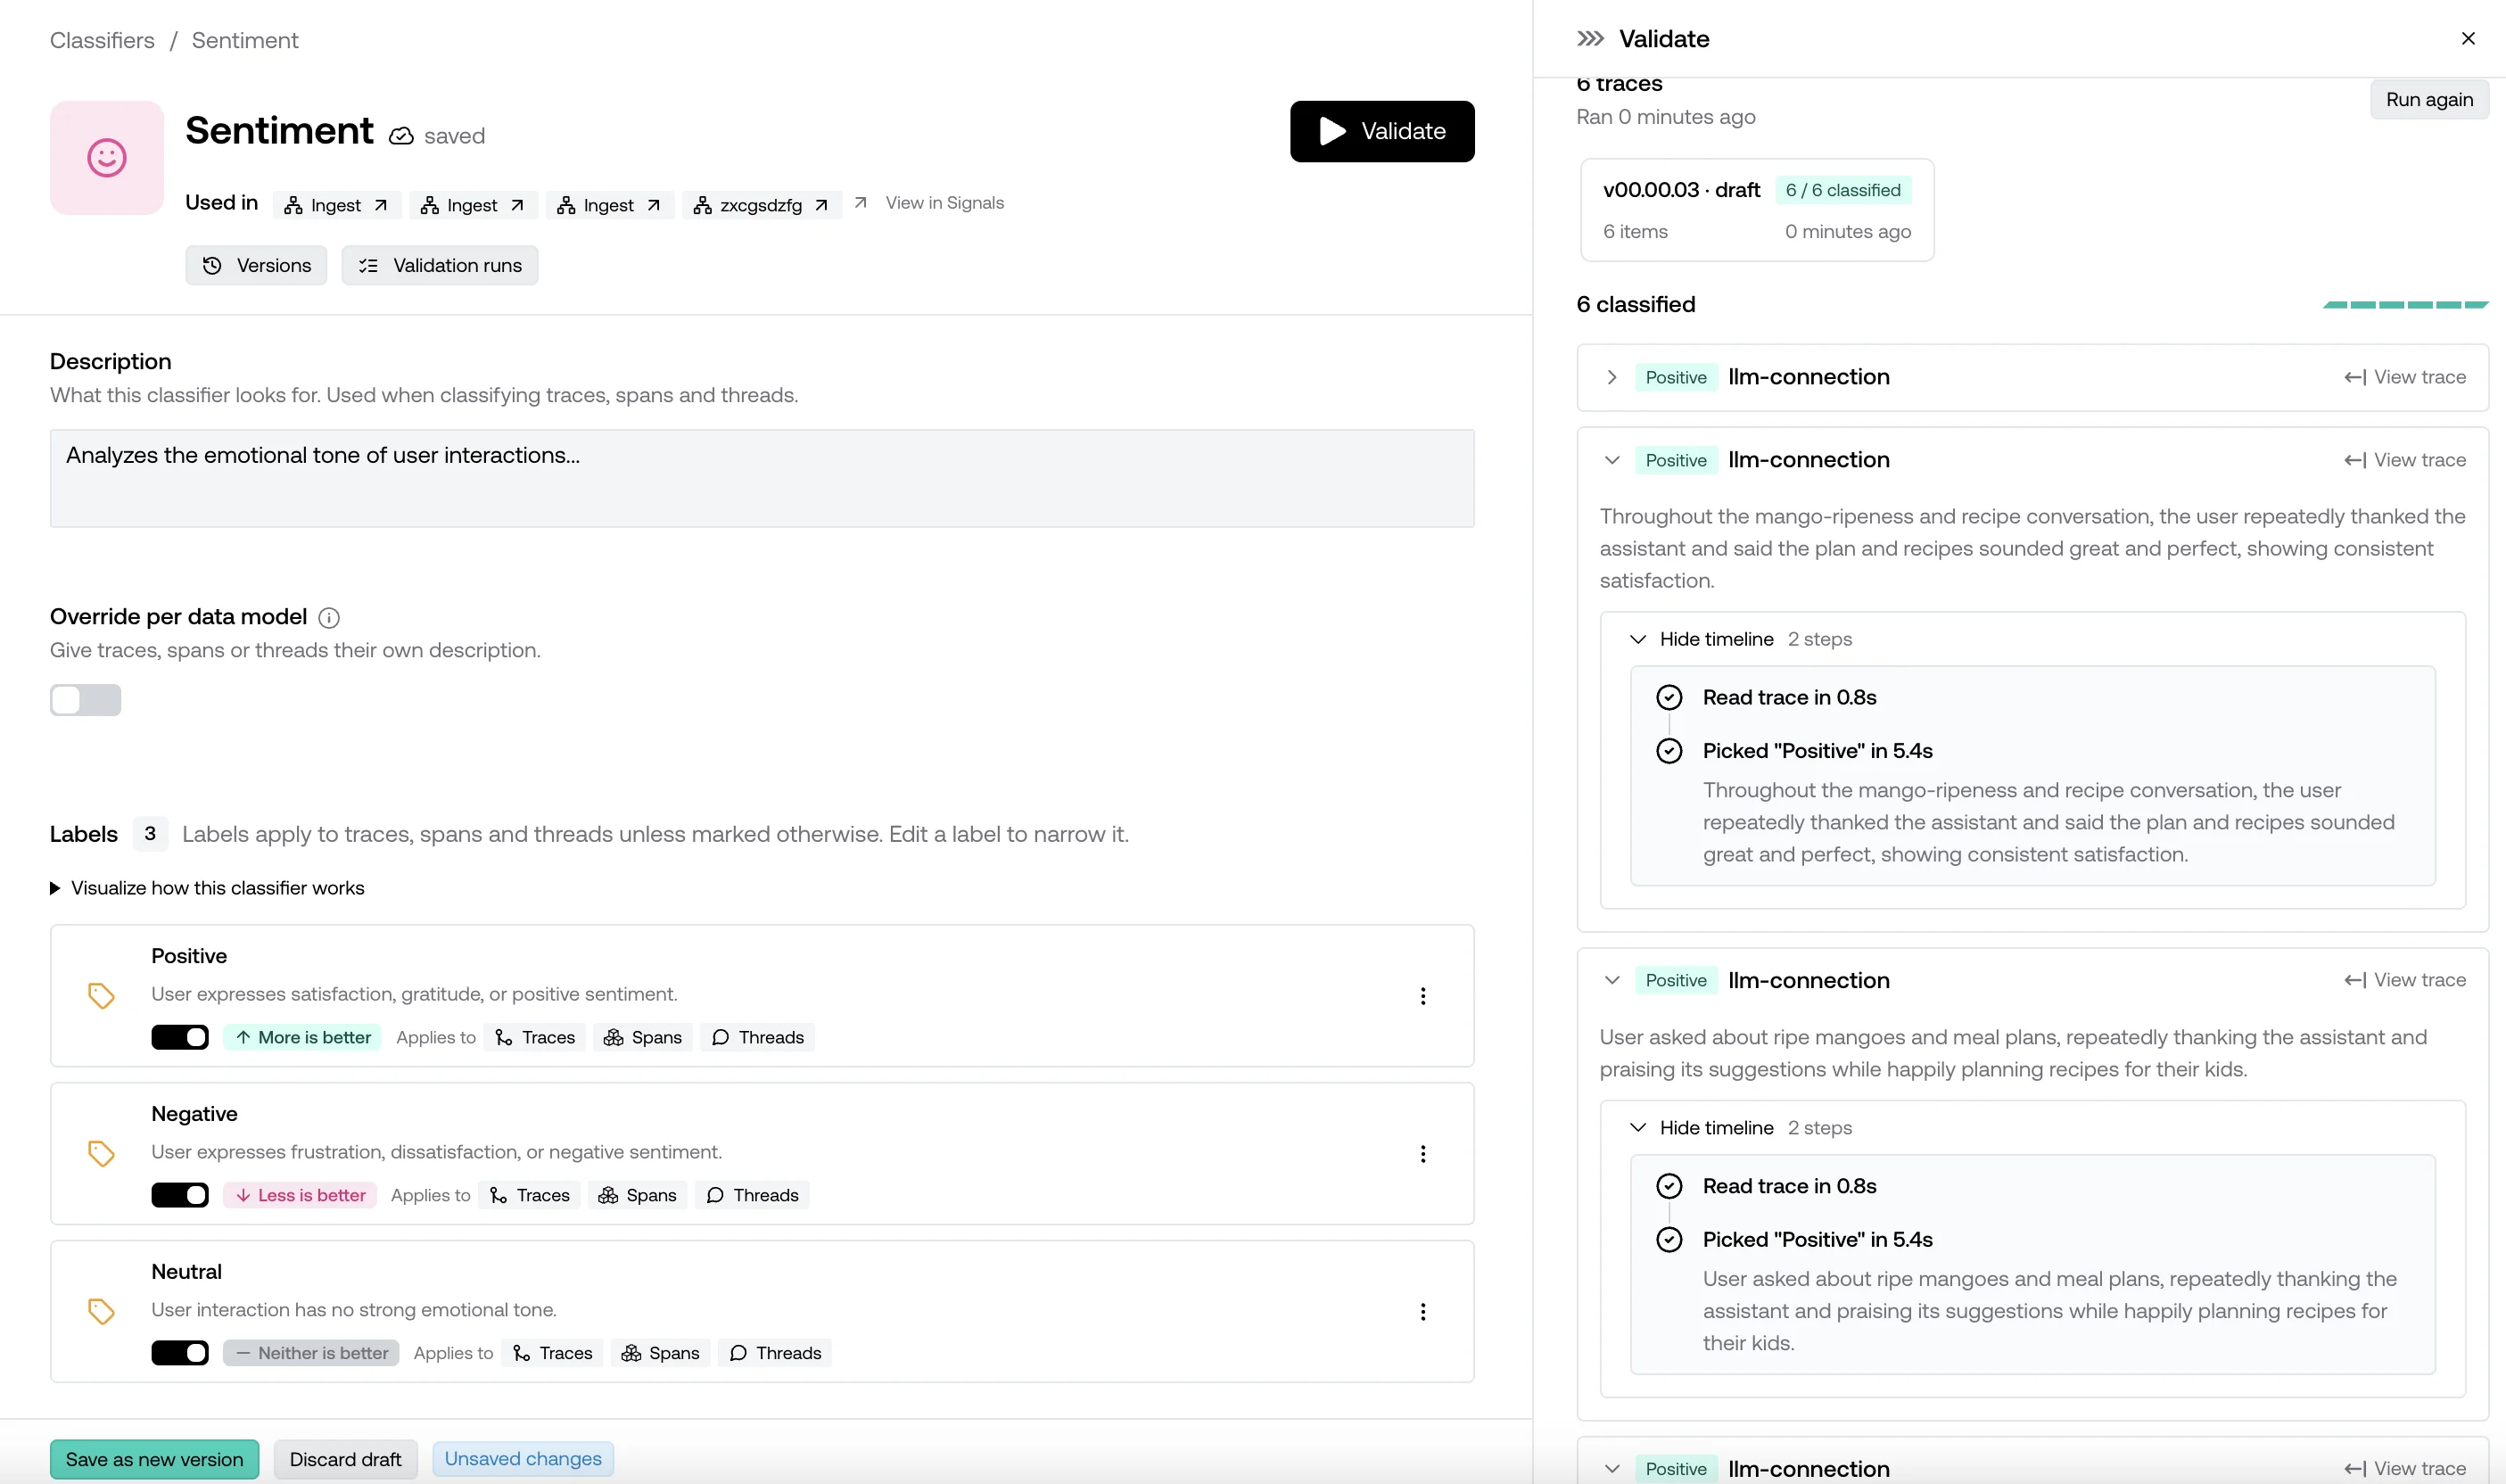
- Classifier Timelines with Step-by-Step Reasoning - Classifiers now show a timeline of their steps, with the reasoning behind the decision at each one. Classified decisions, fully declassified.
- Eval Mode for Classifiers - Classifiers now have an eval mode, so you can switch how a classifier decides between a plain LLM judgment and G-Eval. Two judges, one classifier. Order in the court.
- New LLM Span Attributes - LLM spans now capture cache tokens, reasoning tokens and text, temperature, top-k, top-p, streaming, reasoning effort, output type, time to first token, and image tokens. Things are heating up, and yes, we're tracking the temperature too.
Security
- Encrypted Credentials - Model credentials, AI connection credentials, and voice connection credentials are now encrypted. Your keys, under lock and key.
Changed
- Red Teaming Moves to the Organization Level - Red teaming now lives at the organization level instead of inside a single project. Red teaming got a promotion.
- Multi-Turn Evals Without Simulations - Fixed multi-turn evals that run without simulations. Back in turn.
- Golden & Metric Editor Updates - The golden editor and metric editor now handle labels and persona selection better. Small edits, big personality.
- Browser Translate No Longer Breaks the UI - Chrome's translate feature, or any browser's, no longer breaks the page. Nothing gets lost in translation.
That's the drop for this week. Loud, clear, and fully traced. See you next Friday. Over and out!