


October 9, 2026
- Observability
- Evals
- Human Feedback
- Integrations
- Quality of Life
Tool Me Once, Shame on You
TGIF! Thank god it's features, here's what we shipped this week:
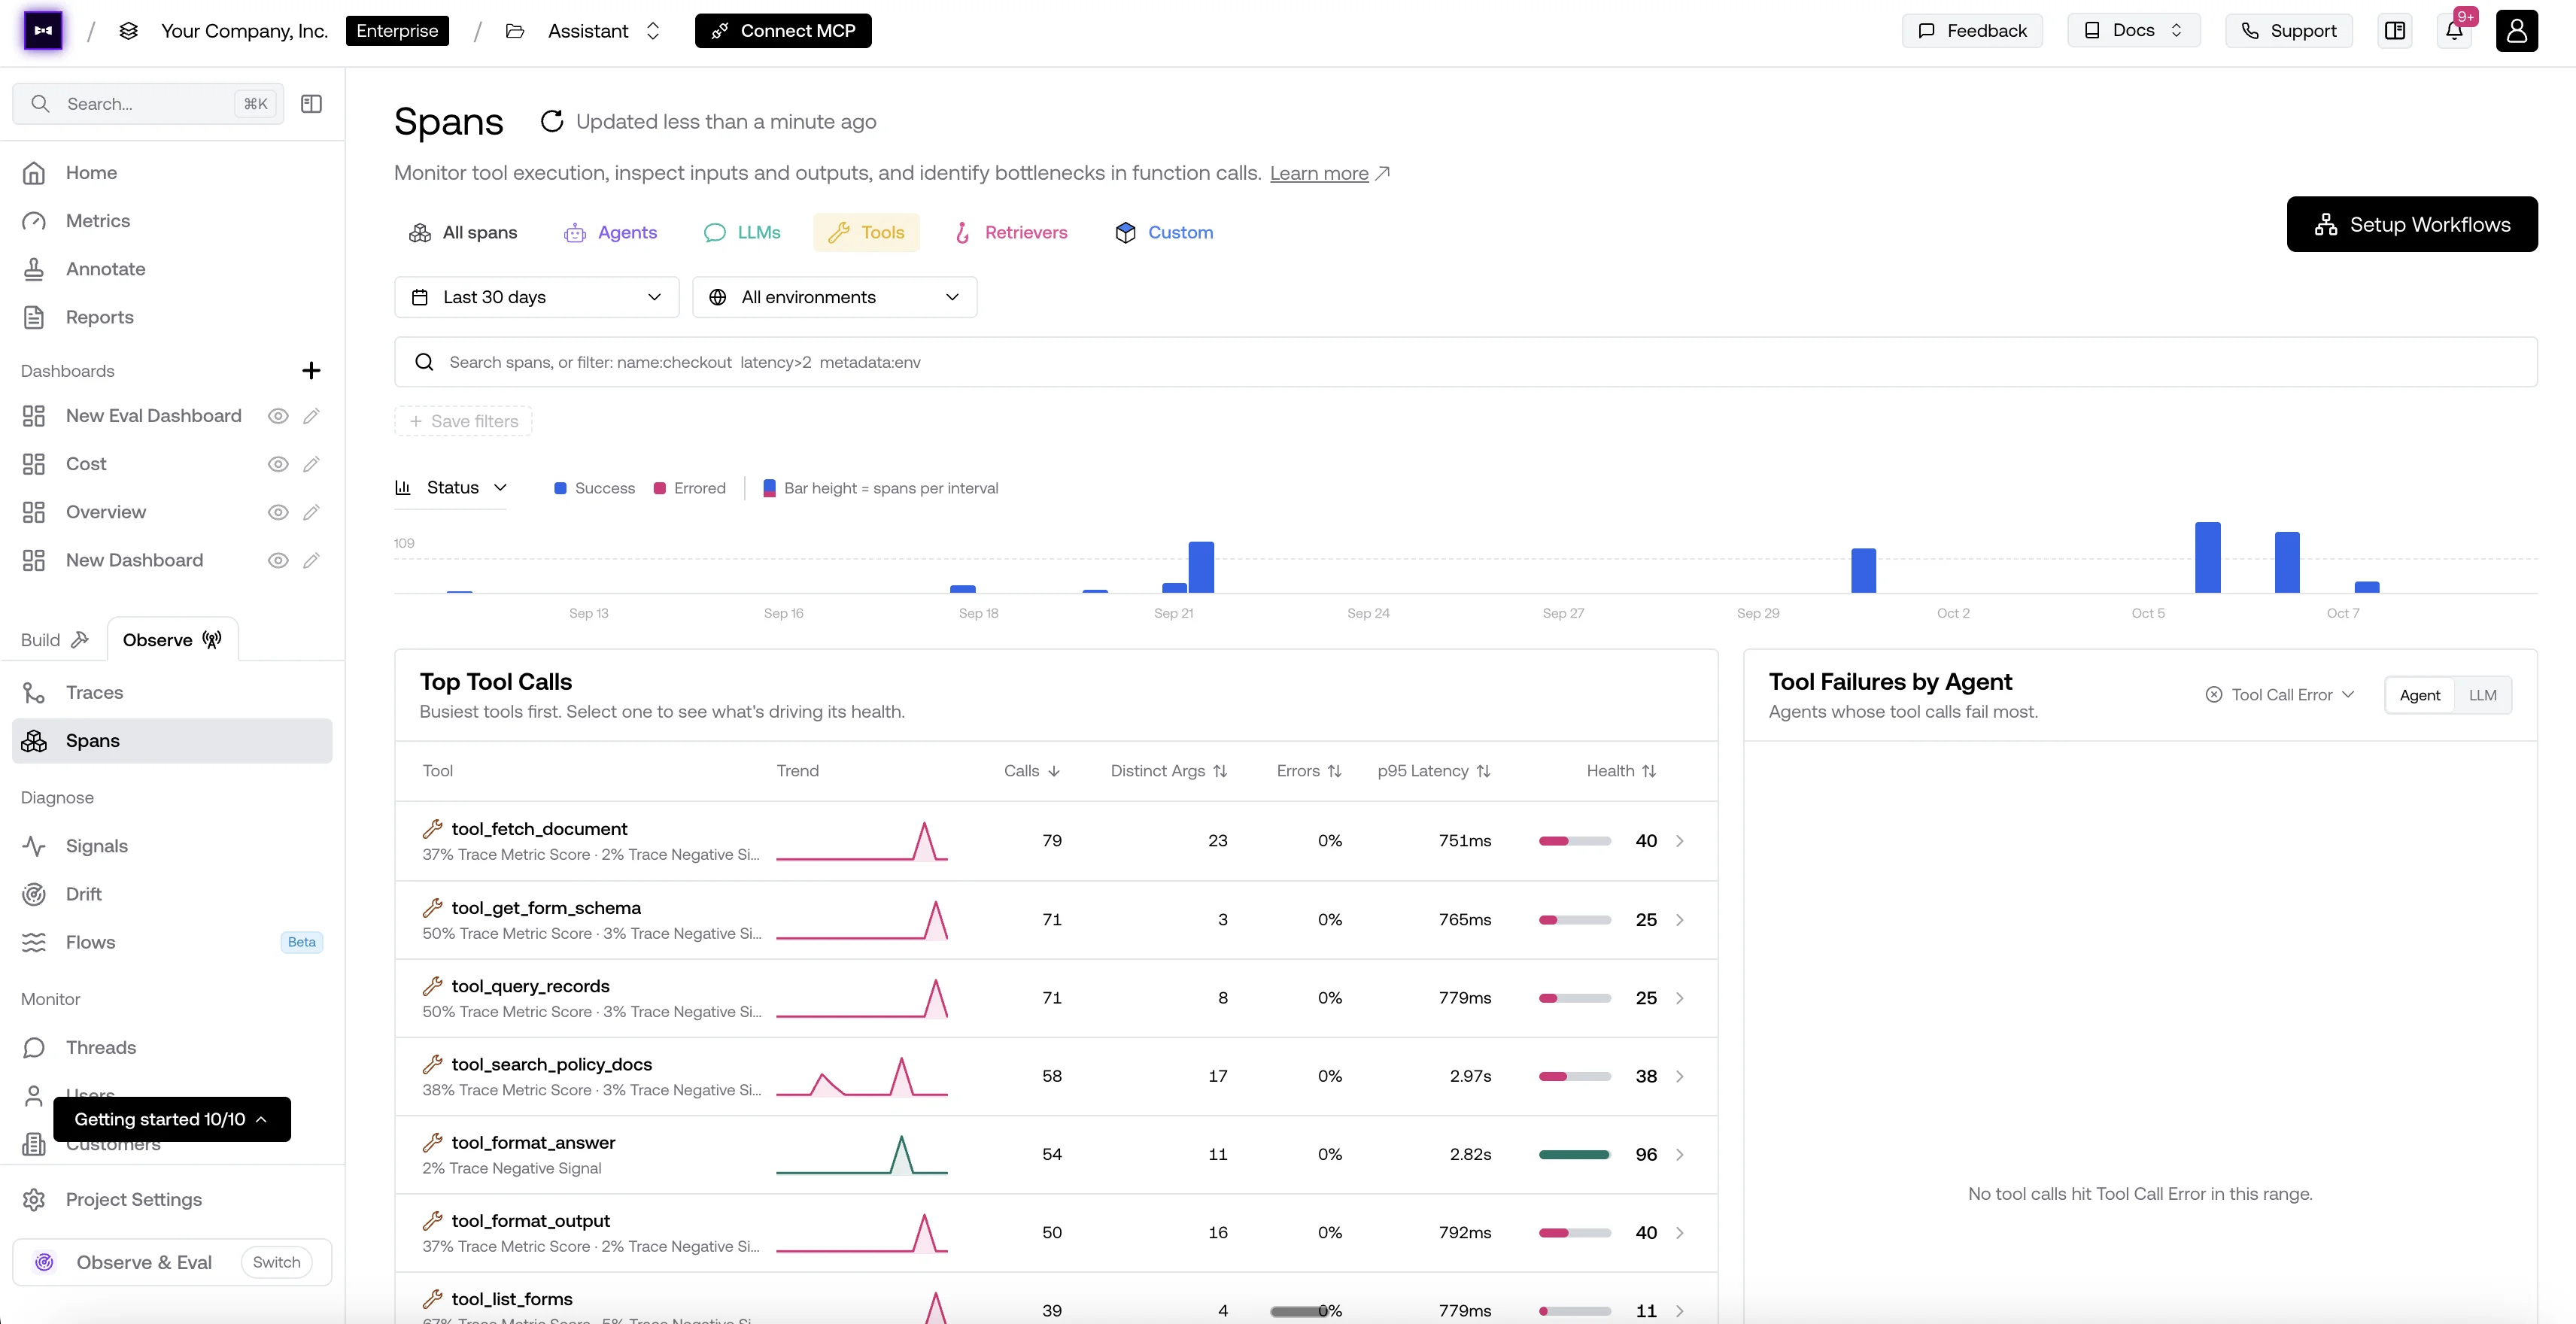
Tool me twice, and now there's a chart for it. Tool Failure Analytics shows which tool errors the most, which arguments get passed the most, and which agent keeps grabbing a hammer for a screw-shaped problem. No more reading traces one by one to work out who the repeat offender is. Your agents can keep making mistakes, they just can't make them anonymously anymore.
Added
- Tool Failure Analytics - See which tool fails most often, which arguments get called most frequently, and which agent is most likely to pick the wrong tool. Find out whether the tool is broken or the agent is just being a tool. And when the team disagrees about what went wrong, you can finally settle the argument.
- Workflow Chains for Classifiers & Ingestion Tasks - Classifiers and ingestion tasks can now kick off workflows, so labeling a trace or filling a queue sets off whatever comes next. Break the chain of manual clicks by starting a better one. The only chain mail you'll actually want to forward.
- Span Trees - Trace trees show you the whole run. Span trees let you pick out one span, like a single subagent, and look at just its branch. Subagents used to get lost in the woods; now each one gets its own family tree. Leaf no subagent behind.
- Revamped Trace Message & IO Views - The message view and the input/output view on traces have been rebuilt, so conversations read like conversations and payloads stop running together. See what went in, see what came out. I/O, I/O, it's off to debug we go.
- Validation Data in Eval Human Alignment Graphs - Human alignment graphs now include validation data, so you can see how well your metric agrees with your reviewers right next to the chart. Your validators were checking everyone else's work, and now someone checks theirs. Everybody needs a little validation sometimes.
- Test Cases in Annotation Queues - Annotation queues now take test cases as well as traces and threads. Reviewers can score your eval results in the same place they review production. Your test cases finally get their day in court. Case closed.
- Persona Metadata Keys in AI Connection Payloads - Persona metadata keys can now be interpolated into your AI connection payload, so each simulated user brings its own context to your endpoint. Personas used to all sound the same. Now every one of them has a key personality.
- More Flexible Golden Schemas for AI Connections - Golden schemas on AI connections now come with an inline editor and viewer, and can include the latest user turn, test cases, or a turn ID in the payload. The golden rule of payloads: send it the way your endpoint wants it. Absolutely schema-zing.
- Prompt-Based Evaluator - A new evaluator that runs on a prompt you write. If you can describe what good looks like, it can grade it. Grading has never been so prompt.
- Z.ai Models - Z.ai models are now supported on Confident AI. Our model lineup officially runs from A to Z.ai, so you can stop catching Z's waiting for it.
That's the drop for this week. No tools were harmed in the making of this changelog, but a few were called out. See you next Friday.